AIHubMix Blog

Announcements, tutorials, model analysis, and product updates from AIHubMix.

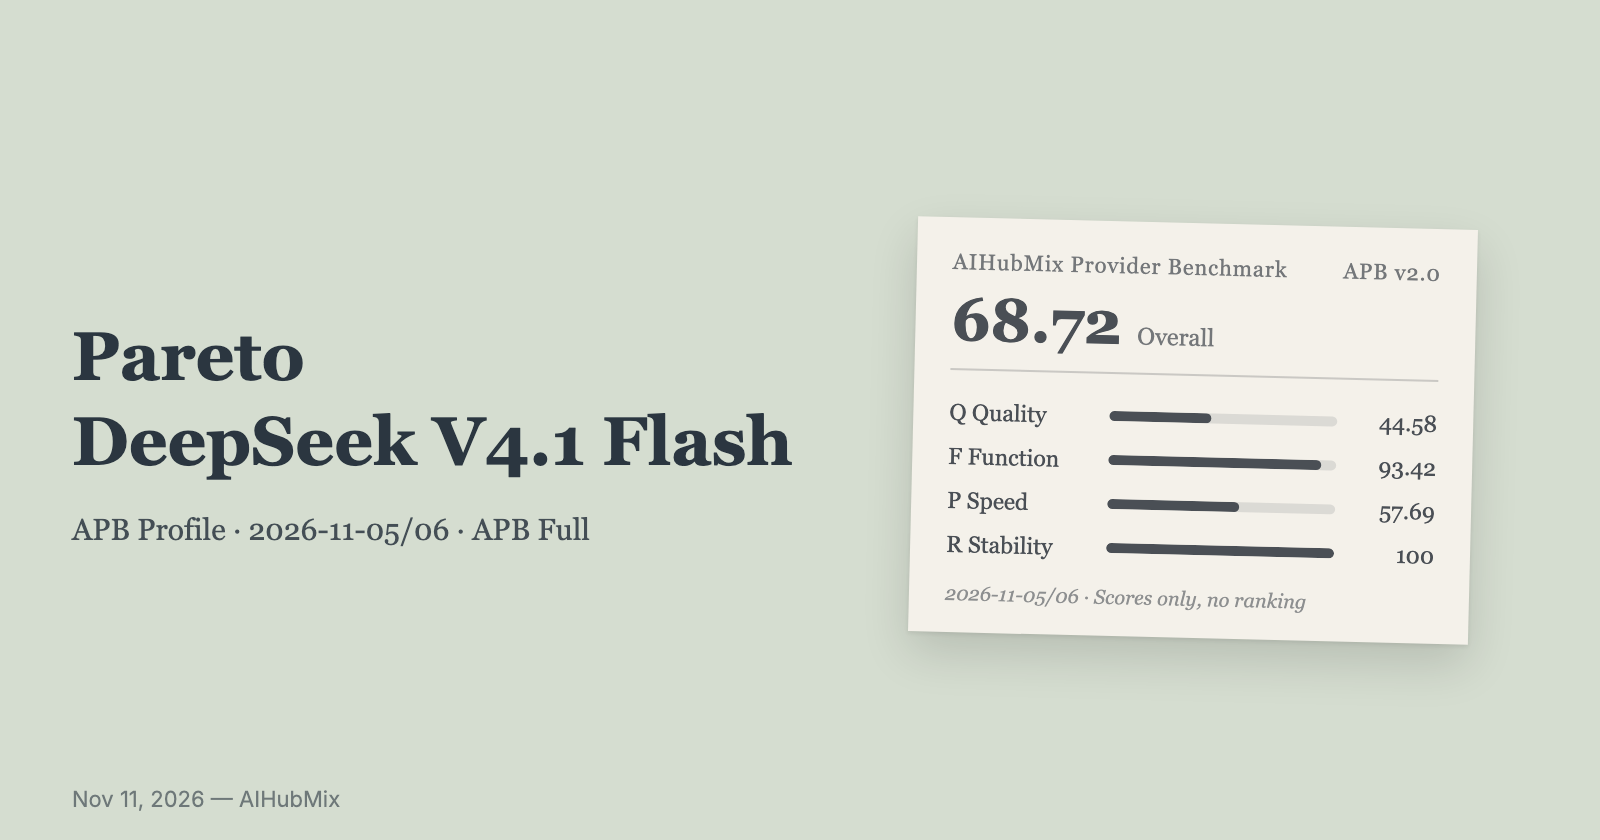
  • Pareto DeepSeek V4.1 Flash review: only 5 hits in 18 hot requests, answers indistinguishable from official

    Pareto DeepSeek V4.1 Flash review: only 5 hits in 18 hot requests, answers indistinguishable from official

    In the 2026-11-03/04 APB Full run, Pareto's four scores are Q 44.58, F 93.42, P 57.69 and R 100, with an overall of 68.72. The 8k hot requests hit 2 of 9 and 32k hit 3 of 9. On 2026-11-03/04, DeepSeek V4.1 Flash 1017 was tested on six providers through AIHubMix with the APB Full suite, using the same questions, parameters and request scripts for each. This APB Profile covers Pareto only: what each section measured and how it came out. The numbers below are scores, not a ranking or a provider

    11 min readProvider Benchmark
  • Gemini 4 Carbon vs Fable 5.2: Which One for Agentic Coding?

    Gemini 4 Carbon vs Fable 5.2: Which One for Agentic Coding?

    Anthropic released Claude Fable 5.2 on November 9, 2026. Google took Gemini 4 Carbon to general availability one day later. Anthropic's own launch benchmark table includes a Carbon column, which makes this a useful comparison for the same long-horizon coding workload. Both models are sold for the same job: long-horizon agentic coding. The agent reads a repository, edits several files, runs commands, reads test output, and keeps going for 15 to 45 minutes without a human turn. That is the task

    10 min readOpinion
  • Gemini 4 Carbon API Migration: 400 Errors, Timeouts and Output Limits

    Gemini 4 Carbon API Migration: 400 Errors, Timeouts and Output Limits

    Gemini 4 Carbon is a drop-in replacement for Gemini 4 Argon at the request-schema level. The same chat-completions body works: the model ID changes and a few parameter values do not survive. The failures that matter sit one layer down — parameter errors that return 400, output limits that truncate silently, and a timeout and billing profile built around long thinking. Four defaults decide the first week: * Keep max_tokens at 65,536 or below on AIHubMix; the model page lists a 65,536-token m

    10 min readTutorial
  • Gemini 4 Carbon vs Argon: Same Price, When Is Carbon Worth It?

    Gemini 4 Carbon vs Argon: Same Price, When Is Carbon Worth It?

    Gemini 4 Carbon is not a new model family. It is Gemini 4 Argon with more thinking per turn, sold at the same per-token price: $2 per million input tokens and $10 per million output tokens on introductory rates through November 30, 2026, then $4 and $20 from December 1. The question is not which model is cheaper per token. They are identical. The question is whether the extra thinking buys enough per completed task to justify a slower first response. Artificial Analysis's live numbers give a c

    10 min readNews
  • Qwen4-Max API: pricing, thinking settings, and caching

    Qwen4-Max API: pricing, thinking settings, and caching

    Qwen4-Max is available through a standard token-priced API. The practical starting point is a 1M-token context, text, image, and video input, and an output budget that includes reasoning as well as the final answer. Before choosing an output cap, decide how much room the model needs to think. Alibaba's Qwen4-Max model page lists the model as its latest multimodal flagship. On AIHubMix, use qwen4-max with Chat Completions at https://aihubmix.com/v1. The gateway guide lists that endpoint; its de

    5 min readTutorial
  • Kimi K3.1 Pro Limited Offer: $1.80 In / $9.00 Out Through Nov 23

    Kimi K3.1 Pro Limited Offer: $1.80 In / $9.00 Out Through Nov 23

    Kimi K3.1 Pro is available on AIHubMix under the model ID kimi-k3.1-pro. The model page lists both a regular rate and a limited promotional rate: during the offer, input is $1.80 / 1M tokens and output is $9.00 / 1M tokens, which is 10% off the regular $2.00 / $10.00 rates. The promotional prices are marked valid through 2026-11-23. The context window is 1,048,576 tokens (about 1M), aimed at coding and agent workflows that need a long working set. This post is a pricing and usage note, not an

    3 min readOpinion
  • Claude Code provider switch: a CC Switch tutorial in 5 minutes

    Claude Code provider switch: a CC Switch tutorial in 5 minutes

    This tutorial follows CC Switch v4.0.26 (November 2026). Button labels may change in later releases; the configuration model is stable. Switching Claude Code between providers usually means editing ~/.claude/settings.json: the base URL, the API key, and sometimes the model. With one provider that is manageable. With two or three, it becomes a small maintenance job — and the failure mode is quiet, because a stale ANTHROPIC_* export in your shell can override the file you just edited. CC S

    9 min readTutorial
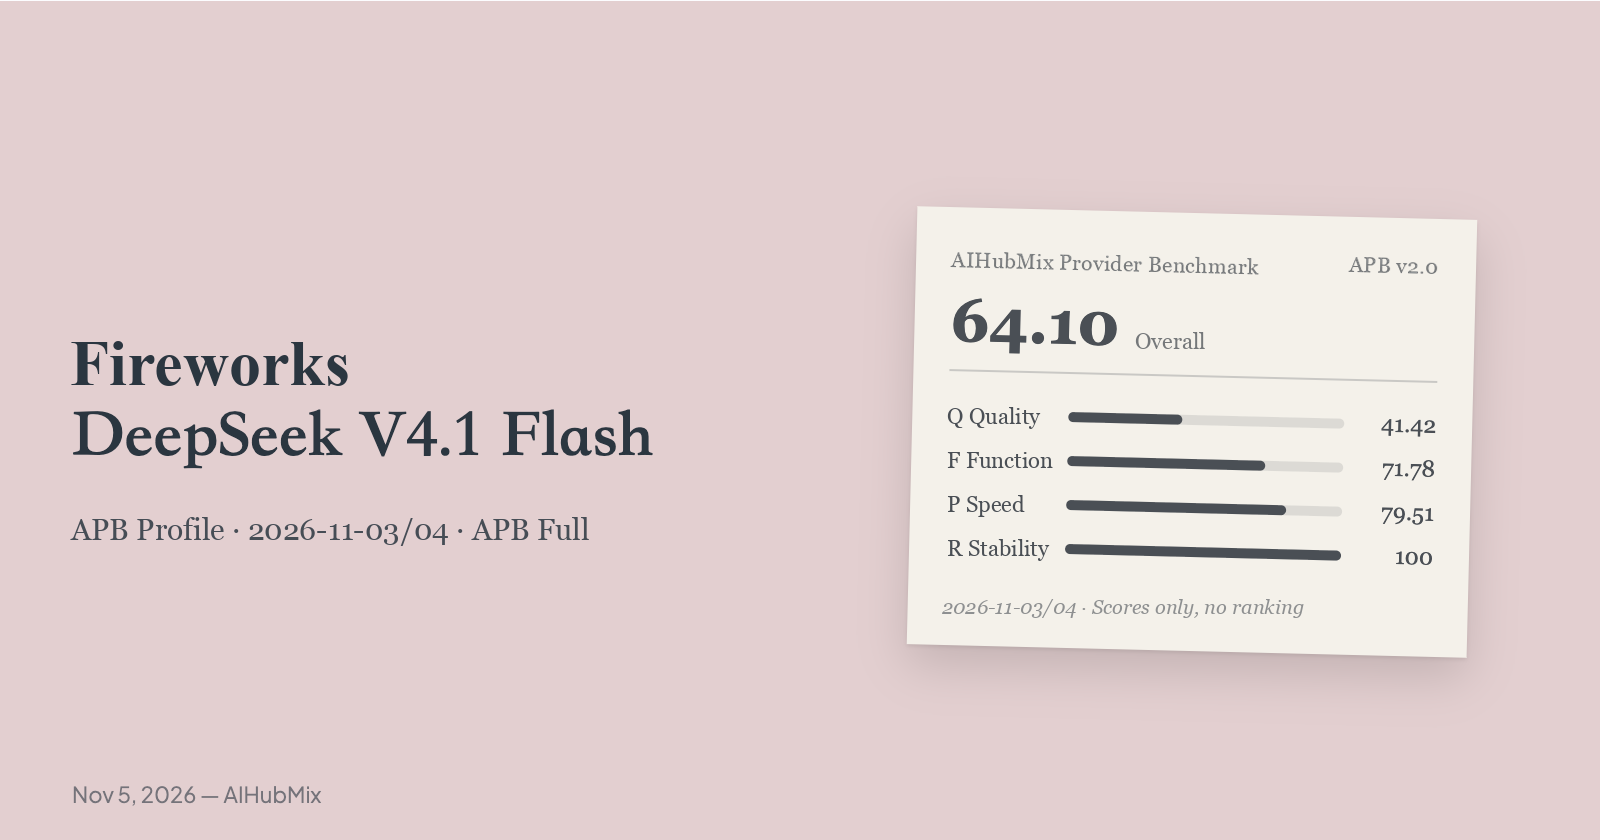
  • Fireworks DeepSeek V4.1 Flash review: stop requests return empty body, 8k cache hot requests hit 3 of 9

    Fireworks DeepSeek V4.1 Flash review: stop requests return empty body, 8k cache hot requests hit 3 of 9

    In the 2026-11-03/04 APB Full run, Fireworks' Q is 41.42, and the 95% interval of its gap to the official channel includes 0. F is 71.78: requests with a stop sequence returned an empty body, the APB v2 parameter-contract check failed, and reported input tokens do not match the native count. K is 60.68. On 2026-11-03/04, DeepSeek V4.1 Flash 1017 was tested on six providers through AIHubMix with the APB Full suite, using the same questions, parameters and request scripts for each. This APB Prof

    13 min readProvider Benchmark
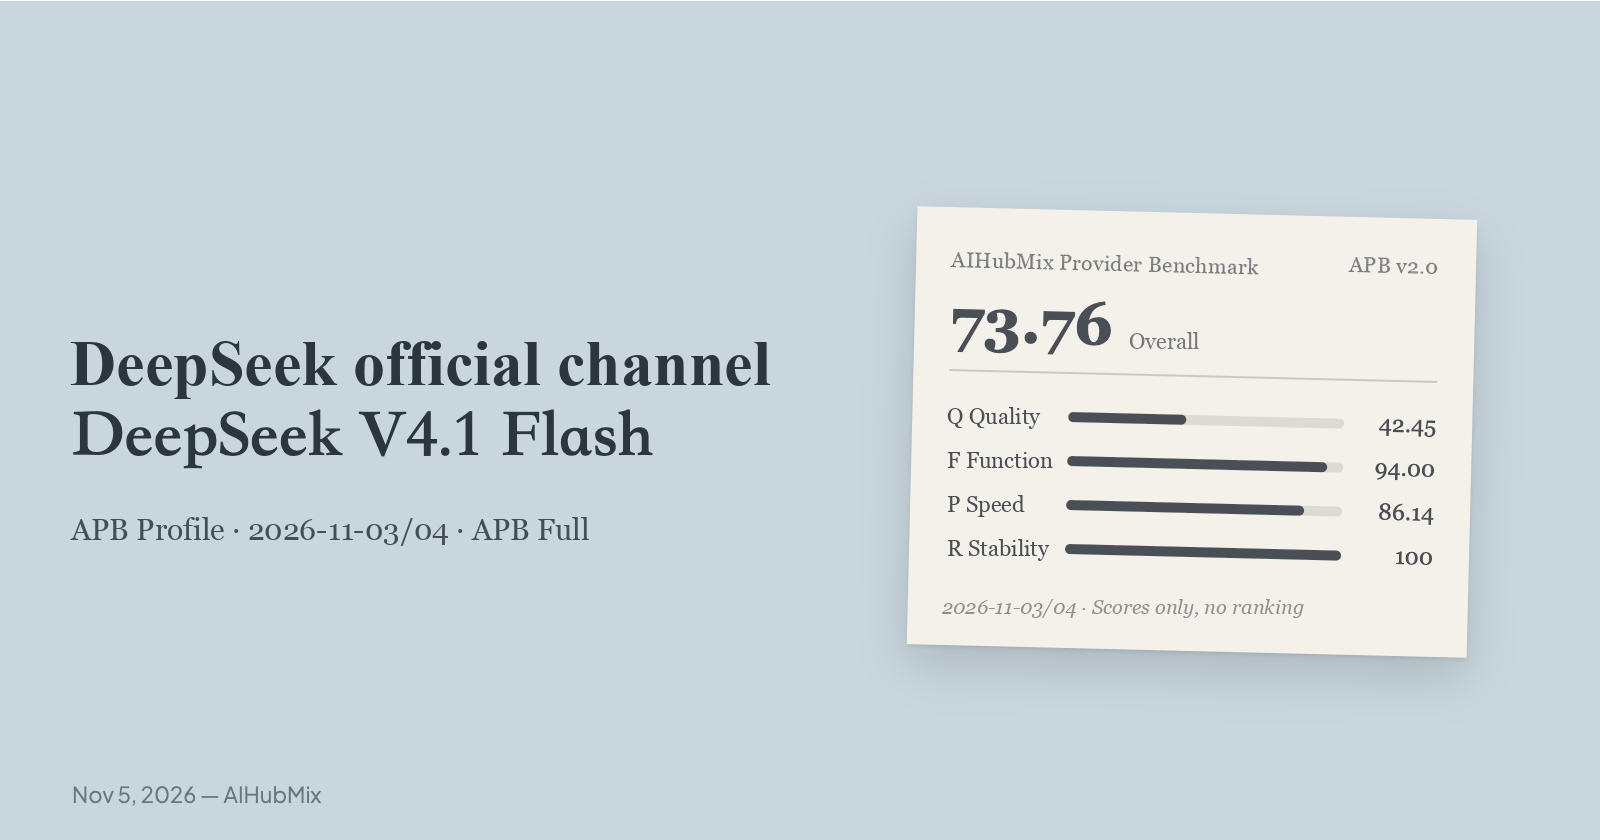
  • DeepSeek official channel DeepSeek V4.1 Flash review: comparison baseline, 15 invalid requests at single concurrency

    DeepSeek official channel DeepSeek V4.1 Flash review: comparison baseline, 15 invalid requests at single concurrency

    In the 2026-11-03/04 APB Full run, the DeepSeek official channel is the answer-quality baseline. Its four scores are Q 42.45, F 94.00, P 86.14 and R 100, with an overall of 73.76, only 0.37 from Alibaba Cloud: not distinguishable. Fifteen single-concurrency speed requests in window 1 were invalid. On 2026-11-03/04, DeepSeek V4.1 Flash 1017 was tested on six providers through AIHubMix with the APB Full suite, using the same questions, parameters and request scripts for each. This APB Profile co

    12 min readProvider Benchmark
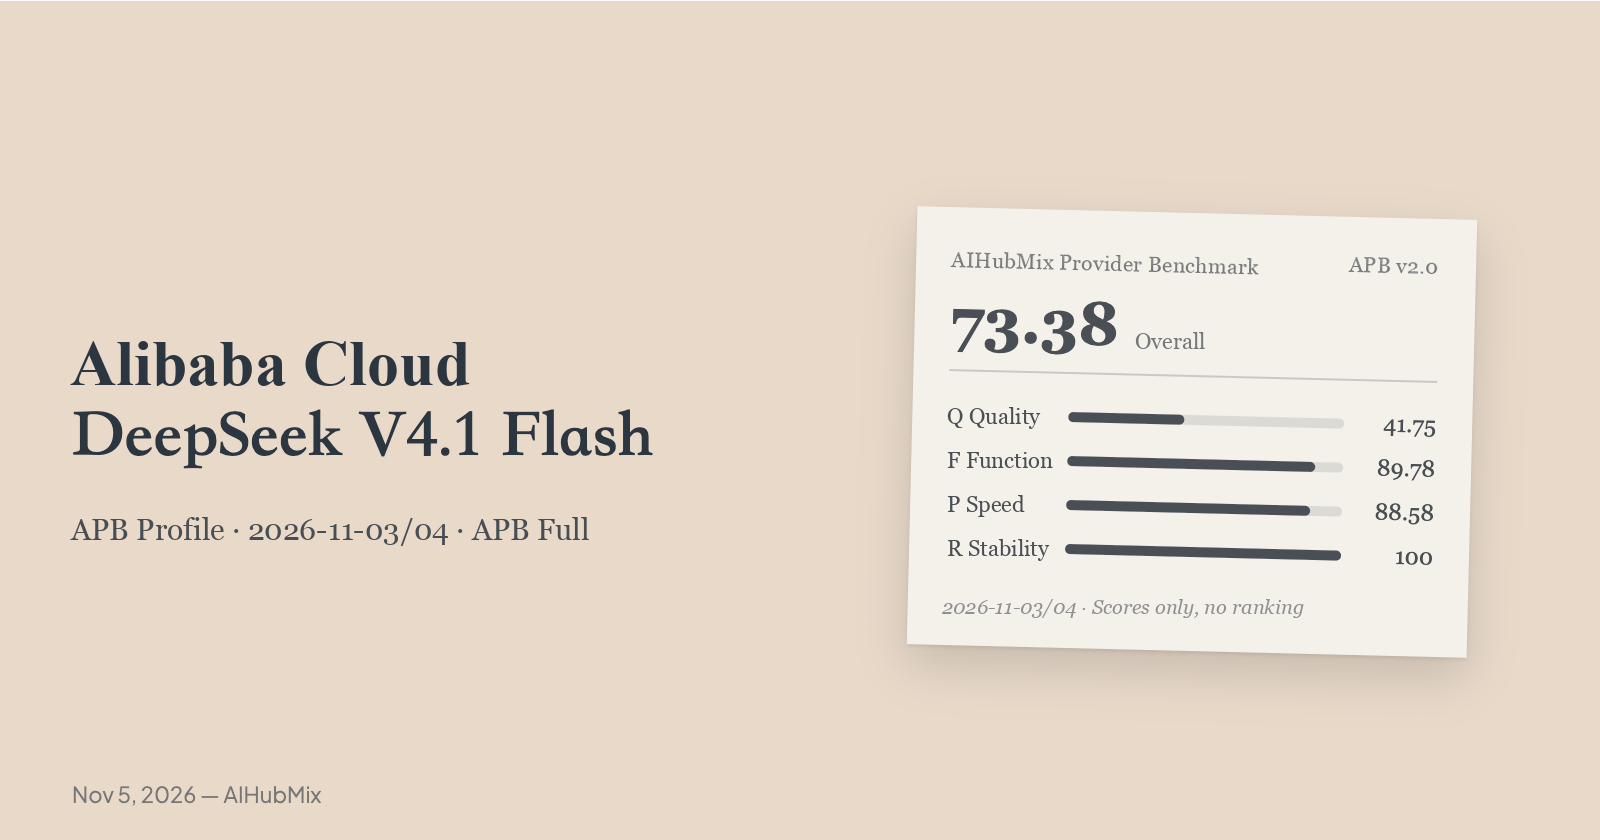
  • Alibaba Cloud DeepSeek V4.1 Flash review: 1.34s first body token, all 18 hot requests hit cache, answers indistinguishable from official

    Alibaba Cloud DeepSeek V4.1 Flash review: 1.34s first body token, all 18 hot requests hit cache, answers indistinguishable from official

    In the 2026-11-03/04 APB Full run, Alibaba Cloud's four scores are Q 41.75, F 89.78, P 88.58 and R 100, with an overall of 73.38. That is only 0.37 from the DeepSeek official channel's overall, and the 95% interval of the Q gap includes 0: the two cannot be told apart. On 2026-11-03/04, DeepSeek V4.1 Flash 1017 was tested on six providers through AIHubMix with the APB Full suite, using the same questions, parameters and request scripts for each. This APB Profile covers Alibaba Cloud only: what

    12 min readProvider Benchmark