
Gemini 4 Carbon is a drop-in replacement for Gemini 4 Argon at the request-schema level. The same chat-completions body works: the model ID changes and a few parameter values do not survive. The failures that matter sit one layer down — parameter errors that return 400, output limits that truncate silently, and a timeout and billing profile built around long thinking.
Four defaults decide the first week:
- Keep
max_tokensat 65,536 or below on AIHubMix; the model page lists a 65,536-token max output and does not publish the larger native path. - For Google native Interactions/background runs, set
store=trueand an explicitmax_output_tokens; these fields are not documented for Carbon on AIHubMix. - Raise HTTP read timeouts to 15–20 minutes per stream when using the vendor-native long-decode path.
- Remove
temperature,top_p, andtop_k, which are ignored, and penalties, pluscandidate_countvalues above 1, which return 400 in Google's Carbon guide.
The unchanged basics — access, security refusals, cost per task — are in the Argon migration post. This post covers Carbon-specific behaviour.
What fails loudly, what fails quietly
Failures divide cleanly: a 400 tells you immediately, a silent cap tells you on the invoice.
| What you see | Class | First move |
|---|---|---|
| HTTP 400 on a parameter | Loud | Remove the unsupported field |
| 400 on a background request | Loud | Add store=true |
| Answer stops at 65,536 tokens | Quiet | Raise max_tokens, up to 65,536 |
| Empty text, status incomplete | Quiet | Raise the cap and retry |
| Background run ends near 64K | Quiet | Set max_output_tokens |
| Answer looks shallower | Quiet | Set the thinking level explicitly |
| Bill above the estimate | Quiet | Count thinking and decode hops |
AIHubMix lists gemini-4-carbon at $2 input, $10 output, and $0.10 cached per million tokens — Google's introductory rates — and documents four protocol surfaces for it. They are temporary; see billing.
Loud failures: the documented 400s
Many documented 400s are parameter validation; history and prefilled model turns are request-state failures. The rules below are from Google's native Carbon guide unless stated otherwise; AIHubMix documents Chat Completions, Messages, Responses and native Gemini for Carbon. AIHubMix's Carbon listing describes the class in one line: "400 — parameter error; most are passed through from the upstream provider." That describes the gateway, not a test. Details come from Google's Carbon guide and what's-new page.
| Trigger | What you see | Fix |
|---|---|---|
| max_output_tokens > 1M* | 400; over cap | Native ≤1M; gateway ≤65K* |
| frequency/presence penalty | 400; unsupported | Remove fields |
| candidate_count > 1 | 400; multi-candidate | Omit or set to 1 |
| background without store* | 400; store required* | Add store=true |
| History ends with model | Rejected; unsupported | End on user turn |
| both controls | 400; cannot combine | Send one |
| thinking_budget or MINIMAL | 400; Carbon guide | Use low/medium/high |
Google prints the message exactly: "store=true is required for background interactions." * Google native only: max_output_tokens is capped at 1M and background requires store=true; AIHubMix lists background mode as a capability but does not document these fields. Use ≤65K on its documented paths.
The minimal row has two meanings. In Google's native Carbon fields, thinking_budget and thinking_level=MINIMAL return HTTP 400; use low, medium or high. In Google's OpenAI compatibility layer, reasoning_effort=minimal maps to low; AIHubMix's model data lists effort values low/medium/high with a medium default, but whether the reasoning_effort alias is mapped still needs a test.
Tool handling is the related trap. Google's Carbon guide says to prefer sequential tool-execution turns, and AIHubMix documents tool calling for Carbon; the Gemini guide records tool_choice="auto", but forced-tool behaviour beyond auto is unconfirmed.
The smallest safe request on /v1/chat/completions drops what Carbon ignores:
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://aihubmix.com/v1",
    api_key=os.environ["AIHUBMIX_API_KEY"],
)

response = client.chat.completions.create(
    model="gemini-4-carbon",
    messages=[{"role": "user", "content": "Reply with OK."}],
    max_tokens=32768,  # room for thinking plus answer
)
print(response.choices[0].message.content)
If that returns 200, the transport layer is done. The rest concerns answers that never raise an error.
Quiet failures: no error, wrong output, wrong bill
The standard output cap is 65,536; vendor long decode is separate
Carbon's standard output ceiling is 65,536 tokens. On Chat Completions the cap field is max_tokens; Google's native guides call it max_output_tokens. Google's native long-decode path can reach up to 1,048,576 tokens minus the input; 131,072 and 262,144 are examples. Google's what's-new page states the rule: "If you set background: true without defining max_output_tokens, the server stops after 64K tokens." AIHubMix lists background mode as a capability, but the native fields and continuation tokens are not documented.
A vendor-native long decode runs in segments: 64K per hop with background or streaming, 32K per hop non-streaming; one non-streaming REST request stops after 32,768. Google's guide notes that "Earlier SDK versions and the OpenAI compatibility layer can't retrieve long completions using continuation tokens." For AIHubMix, keep max_tokens at or below 65,536 as a conservative, unverified gateway limit; do not plan to stitch longer answers until the model page documents it.
A low cap truncates thinking, and empty output is billed
The cap covers thinking, not just text. Google's long-decode guide says: "A low value, such as 8,192, stops the model before it finishes thinking." The status becomes incomplete, and "Text can be empty if the model was still thinking." You pay either way. Budget for thinking plus answer, and treat an empty incomplete response as a cap problem: raise the limit, retry, and expect the first attempt on the bill.
The thinking default is medium
Carbon defaults to medium, the same as Argon. Teams from Gemini 3.1 Pro Preview, which defaults to high, lose a level without changing code and read the shallower answer as a regression. Google recommends medium for most coding and agentic work. Set the level explicitly in staging, and send only one control field: reasoning_effort and thinking_level cannot be combined.
Sampling parameters are ignored
temperature, top_p, and top_k are ignored — no error, no change in sample. Remove them. Penalties and candidate_count values above 1 return 400.
Explicit caching is gone
cachedContents and caches.create are unsupported. Implicit caching applies at 4,096 tokens and above with a 95% discount. Delete explicit-cache code, keep the stable prompt prefix first, and check cached-token usage before budgeting the discount.
Conversation state has a rule
Google recommends previous_interaction_id for continuation. Chat Completions has no such field, so keep the history but end it on a user turn; a model-role ending or prefilled model turn is unsupported.
Timeouts: 15 to 20 minutes, not 60 seconds
Google's long-decode guide recommends HTTP read timeouts of 15 to 20 minutes per stream; its migration checklist repeats a 15-minute minimum. That recommendation concerns long-decode requests. A separate AA measurement shows the wait for the first answer token: Carbon High took 67.1 seconds, Medium 23.2, Low 12.9 and Argon High 40.1. Does a 60-second cutoff even allow the first token to arrive?
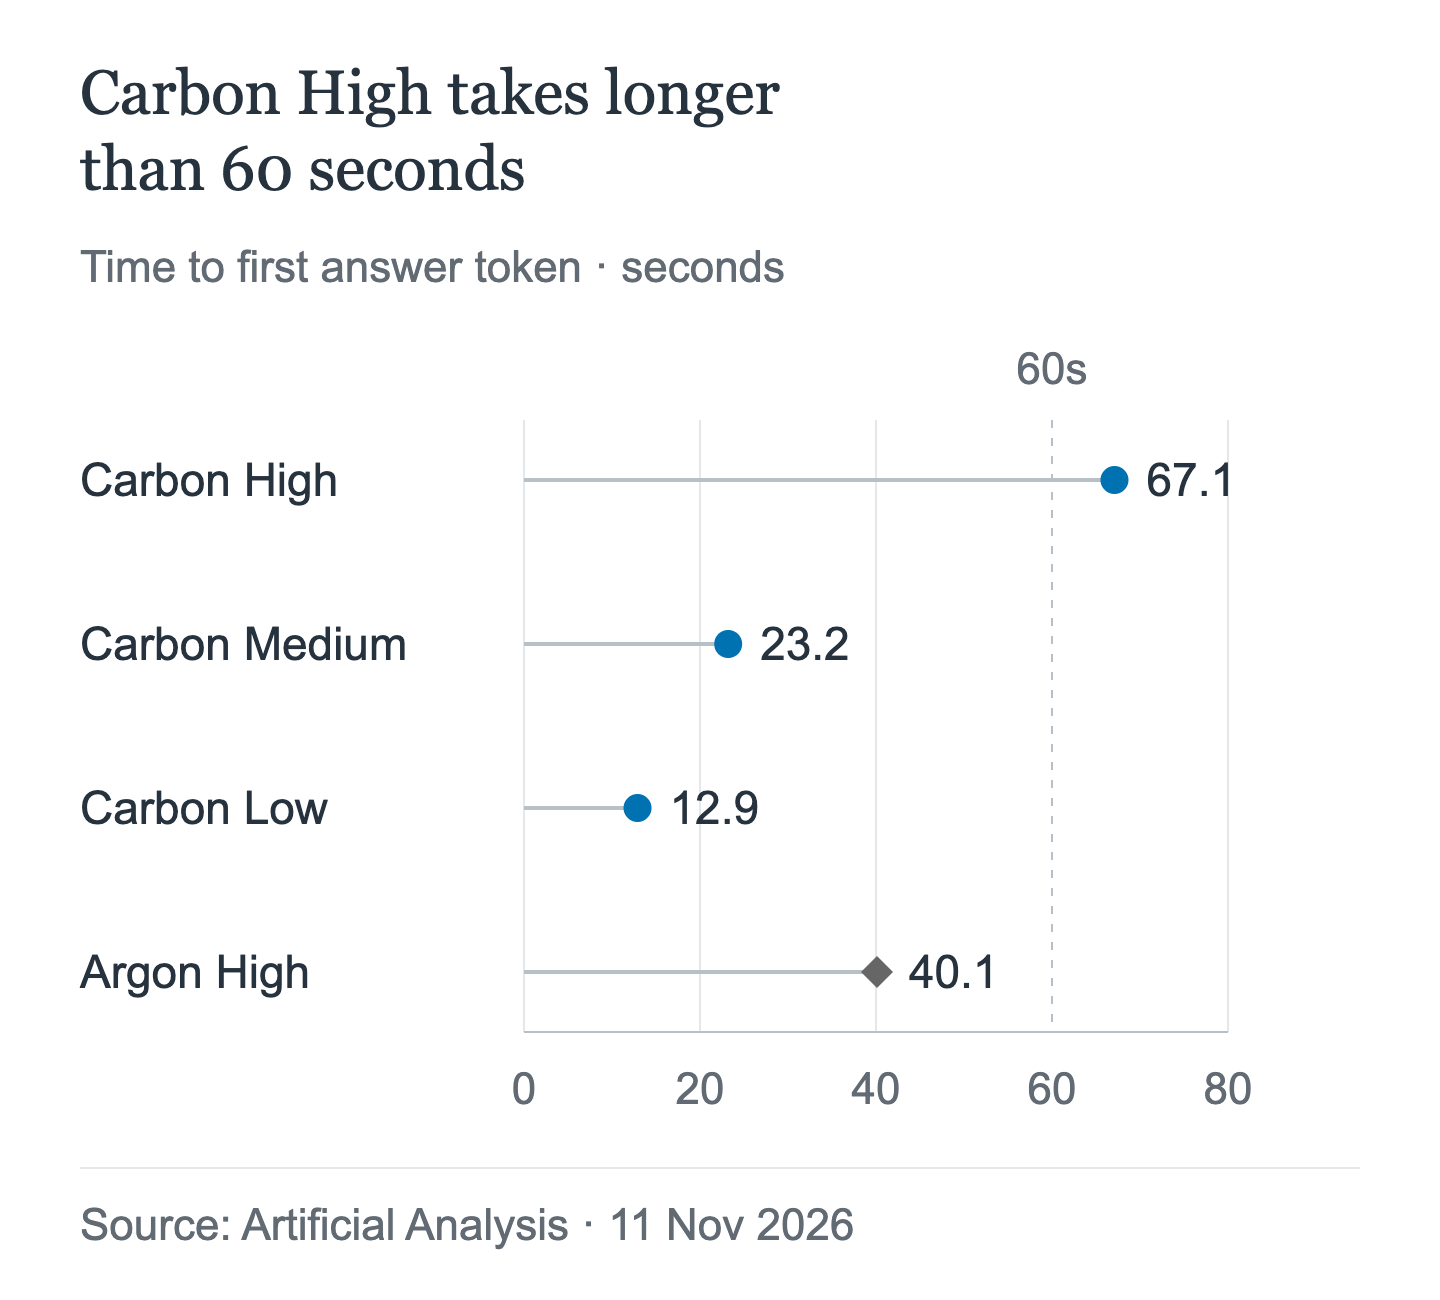
Carbon High exceeds the 60-second reference in this measurement. First-token time does not establish a safe timeout for the whole request: the 15–20-minute advice above comes from Google’s long-decode guide. These are one snapshot’s results, not latency guarantees or an AIHubMix test.
Google's native client hop limits are tighter than its background limit: 20 minutes for a stream, 10 for a non-streaming call, against 24 hours for background. AIHubMix does not document these background limits.
Native SDK minimums for long decode: Python 2.34.0, JS 2.32.0, Go 1.77.0, Java 1.80.0, .NET 1.28.0. Claude Code's API_TIMEOUT_MS defaults to 10 minutes; raise it before the first Claude Code run against Carbon.
Billing traps
Carbon's per-token price is simple; the bill is not. Several mechanisms enlarge an invoice, and one scheduled change doubles every rate.
Thinking is billed as output
Thinking tokens are billed as output. Carbon's output rate is $10 per million tokens now and $20 from December 1.
Every long-decode hop is billed
Google's worked example: a 1,000-token prompt producing 200,000 output tokens reports total_input_tokens of 397,216 across hops of 1,000, 66,536, 132,072, and 197,608. "You pay for every token in every hop, including hops that contain only thinking." Implicit caching discounts most input by 95%, but the hops remain in usage. Completed work is also billed when a run fails or is cancelled: "Completed segments are billed at the end of each segment even if a later segment fails or is cancelled," and "You pay for all work completed before the interaction ends."
Grounding has its own meter
On Google's native service, grounding with Google Search includes 5,000 free requests per month, shared across Gemini 3 and newer, then $14 per 1,000, capped at 1,500 a day. AIHubMix lists web search at $0.014 per request; whether it is the same grounding path needs a test.
The Vertex footnote is vendor-only
Google's Vertex pricing page adds a rule: completions over 32K tokens are charged for retrievable token usage even if the request fails on a client or server timeout, effective November 13, 2026. That is a vendor rule; whether AIHubMix's VertexAI provider applies it is unpublished. Ask before assuming.
December 1 doubles every rate
| Rate | Until November 30 | From December 1 |
|---|---|---|
| Input | $2 per 1M | $4 per 1M |
| Output | $10 per 1M | $20 per 1M |
| Cached read | $0.10 per 1M | $0.20 per 1M |
Carbon and Argon share the introductory rates; every rate doubles on December 1. AIHubMix lists the introductory rates today and has not published its post-December price. Treat the double as certain and the gateway number as unknown, and check both before committing a budget.
Agents with real permissions
For Google-native calls, the Carbon guide says to prefer sequential tool-execution turns. Build one call at a time when using that path. AIHubMix documents tool calling for Carbon and records tool_choice="auto"; forced-tool behaviour on the gateway is unconfirmed.
History must not end on a model turn, and prefilled model turns are unsupported. If a tool result is missing, send a user turn asking for the next step.
The model card lists occasional slowness or timeouts and extra tokens at higher levels; the knowledge cutoff is March 2026. With write access, a timeout is the real risk: a run that exceeds the client limit can leave partial work behind, and completed segments are still billed.
Coding tools: check the model page before wiring anything
AIHubMix's Carbon model page documents Chat Completions, Messages, Responses and Gemini. Claude Code needs Anthropic Messages; Codex needs Responses. Both now have a documented route on Carbon; still smoke-test the exact client, because protocol availability and parameter support are separate questions.
The request shape is the same as Argon, but each client uses a different protocol surface. Carbon's model page documents Chat Completions, Messages, Responses and native Gemini. The Claude Code post covers ANTHROPIC_BASE_URL, ANTHROPIC_AUTH_TOKEN, and API_TIMEOUT_MS; the Codex post covers the provider block, wire_api, and model_reasoning_effort. What changes is which tab of the model page applies.
| Client | Protocol it needs | Carbon on AIHubMix |
|---|---|---|
| Claude Code | Anthropic Messages | Documented (Messages) |
| Codex | Responses API | Documented (Responses) |
| OpenAI SDK | Chat Completions | Documented |
Settings:
- Model ID:
gemini-4-carbon. - Thinking: low, medium, high; default medium.
- Effort mapping: native field
thinking_level, compatibility fieldreasoning_effort; AIHubMix's model data lists low/medium/high with a medium default, but the alias mapping still needs a test. Send one. - Context: 1,048,576 per Google; AIHubMix's model page lists 1.05M context and a 65.5K max output.
- Known issues: slow first token at high, vendor guidance to prefer sequential tool turns, a documented 65,536-token AIHubMix output cap, and a March 2026 cutoff.
Smoke test, 10–15 minutes:
- Pick a small repository with one failing unit test and a test command that finishes in under a minute.
- Set the model to
gemini-4-carbon,max_tokensto 65,536 or lower, and the HTTP timeout to at least 15 minutes. - Ask the tool to make the smallest change that turns the test green, then run the test command and inspect the diff.
- Pass: the edit is minimal and the test passes within 10–15 minutes. Fail: record whether the response was a 400, an incomplete answer, a timeout, or a bad edit; each has a different fix above.
- If the tool exposes the level, test medium and high, and keep the one that finishes inside the window.
Checklist before the first production request
- Model ID set to
gemini-4-carbon. - No
temperature,top_p, ortop_k. - No
frequency_penaltyorpresence_penalty; keepcandidate_countat 1 or omit it. max_tokensat 65,536 or below.- Google-native background requests send
store=trueand an explicitmax_output_tokens; AIHubMix lists background mode but does not document these fields. - HTTP timeout at 15 minutes or more; streaming preferred.
- Only one of
reasoning_effortandthinking_level. - Prefer sequential tool turns on Google native; AIHubMix lists tool calling and records
tool_choice="auto", but forced-tool values still need a test. - No explicit cache calls; the stable prompt prefix comes first.
- Budget includes thinking tokens and every long-decode hop.
- December 1 rates checked with whoever owns the budget.
- Coding tool checked against the model page before configuration.
FAQ
Does the request body need to change when moving from Argon to Carbon?
No. The schema is unchanged. Change the model ID, review values, and remove fields that now return 400.
Why does max_output_tokens return a 400?
Google's native Carbon API rejects values above 1,048,576. AIHubMix's model page lists a 65,536-token max output, so keep max_tokens at or below that until a larger path is documented. A low value truncates thinking instead, which is worse: the answer can be incomplete and billed.
Why is the response empty?
If the status is incomplete, the text can be empty because the model was still thinking. You pay for the work. Raise the cap and retry.
Why does a background request stop at 64K?
On Google's native background path, omitting max_output_tokens stops the server at 64K. Set the limit explicitly; native long decode can reach up to 1,048,576 minus input. AIHubMix lists background mode as a capability, but does not document the native fields.
Is temperature respected?
No. temperature, top_p, and top_k are ignored. Penalties and candidate_count values above 1 return 400 instead.
Will Carbon cost twice as much on December 1?
Google's rates double: input from $2 to $4, output from $10 to $20, cached reads from $0.10 to $0.20. AIHubMix has not published its post-December price, so confirm before committing a budget.
Can Claude Code or Codex be used with Carbon?
Yes, both have a documented protocol. AIHubMix documents Messages and Responses for Carbon; still smoke-test the exact client and its parameter set.
Keep reading: the Gemini 4 Carbon series
- If the migration is running and the remaining question is whether Carbon earns its price at all, the comparison puts the shared introductory rates side by side.
Gemini 4 Carbon vs Argon: Same Price, When Is Carbon Worth It? - If you are choosing a coding agent rather than migrating an endpoint, the head-to-head covers tool use and cost per task.
Gemini 4 Carbon vs Fable 5.2: Which One for Agentic Coding?


